How do large language models (LLMs) work?

Every chatbot answer is built one guess at a time. Train a real tiny language model on a paragraph about monsoons and chai, watch a tokenizer chop Hindi into bytes, click a word to see what it attends to, and catch the model saying something false with total confidence.

LLMClearOpened 19 Sept 202620 min to playFree · no sign-up

In 60 seconds

  1. A machine that guesses the next word

    A language model gives a probability to every possible next piece of text. Pick one, add it, ask again. Our tiny model learns those odds by counting letters in a 2,100-letter text; temperature and top-k decide how boldly it picks.

  2. Text becomes tokens

    Models read numbered pieces called tokens, built by byte-pair encoding: start from 256 bytes and keep merging the commonest pair. A Devanagari letter is 3 bytes in UTF-8, so a tokenizer trained mostly on English can need several times more tokens for Hindi.

  3. Words become points in space

    Each token is swapped for an embedding, a long list of numbers. Words used in similar company end up close together: chai near coffee, Delhi near Mumbai. The same trick soaks up bias from the text.

  4. Attention: words look at words

    In a transformer, every token makes a query, a key and a value. Queries are matched against keys, softmax turns the scores into shares, and each token takes a mix of the others' values. That is how "it" finds "chai".

  5. Scale, then teaching

    Big models have billions of parameters, trained on trillions of tokens to predict the next one, then tuned on examples and human feedback to be helpful. Compute is about 6 operations per parameter per token, and the energy bill is real.

  6. Fluent is not the same as true

    Because they predict likely text, LLMs can state false things with full confidence, repeat bias and sometimes repeat training text. Give context, ask for sources, check what matters, and keep private data out.

The history

From Markov counting letters in a poem in 1913 to chatbots used by hundreds of millions: a century of predicting the next word.

Read the full history
  1. 1948Fake English from counts
  2. 2013word2vec: words as points in space
  3. 2017"Attention Is All You Need"
  4. 2020GPT-3 and learning from examples in the prompt
  5. 2023Open-weight models: Llama
  6. 2024The EU AI Act comes into force

The full explanation

LLMClear, chapter by chapter

Chapter 1

Predict the next letter

A language model is a machine for guessing what comes next.

Type "the monsoon reaches ker" and you can guess the next letter. So can a machine. A language model is a machine that, given some text, gives a probability for every possible next piece. Pick one, add it to the text, and ask again. Do that a few thousand times and you have written a page.

This one is real and tiny. When the page loaded, it read a short text about the monsoon and chai (about 2,100 letters, written for this box) and simply counted: after "th", how often came "e"? how often "a"? Those counts become the bars. The engineer Claude Shannon played this game in 1948, building fake English from letter counts.

The context is how many letters back it looks. With 1 letter it writes gibberish. With 3 or 4 it writes real-looking words, but it starts to copy its training text word for word, because it has seen so little. Big LLMs look back thousands of tokens and learn patterns instead of storing counts.

Temperature changes how it picks. Near 0 it always takes the tallest bar: safe, but it loops. At 1 it follows the true odds. Above 1 the odds flatten and it gets wild. Top-k throws away all but the k best choices first. Chatbots use the same dials.
Try “Next letter” in the interactive model →

Chapter 2

Text becomes tokens

Before a model reads a word, the word is chopped into numbered pieces.

An LLM never sees letters or words. It sees tokens: numbered pieces of text. "chai" might be one token, "monsoon" two or three, a space-plus-word often one. A big model knows somewhere between tens of thousands and a few hundred thousand tokens.

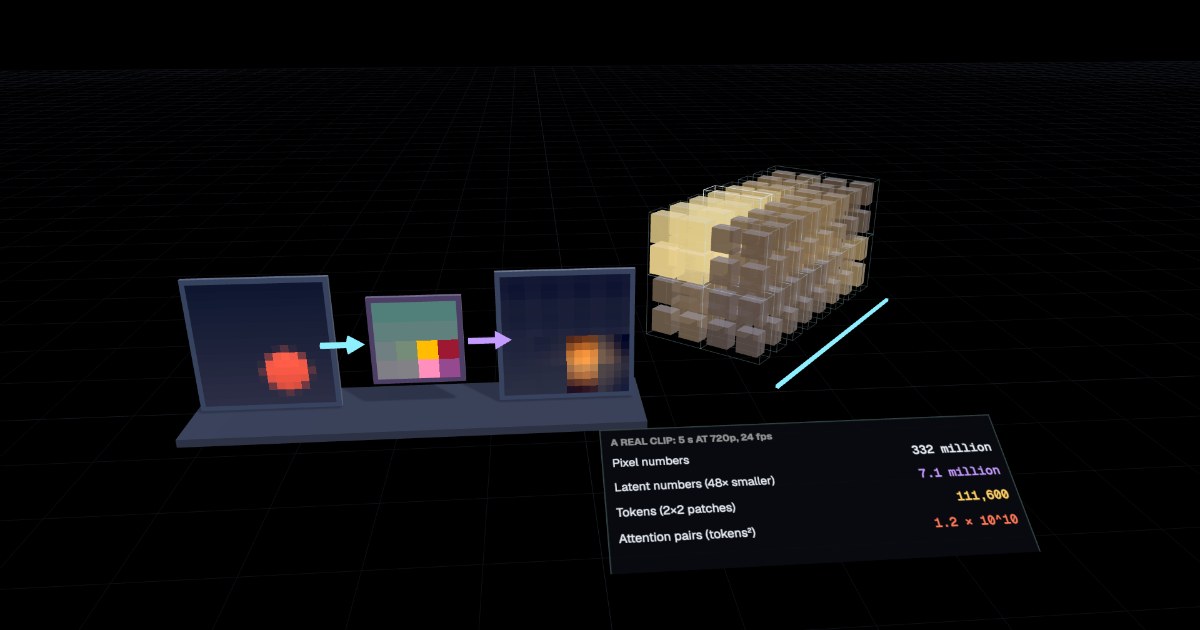
Where do the pieces come from? A method called byte-pair encoding (BPE). Start with the 256 bytes that computers store text in. Find the pair of neighbours that appears most often in the training text, like "t" + "h", and give it a new number. Repeat. After hundreds or thousands of merges, common words become single tokens and rare words are built from parts. This one is trained live on this box's text: watch it merge.

Now try Hindi. In UTF-8, each Devanagari letter or sign takes 3 bytes, against 1 for an English letter. If a tokenizer learned its merges mostly from English, it knows few Hindi pieces, so Hindi falls apart into bytes: about 3 tokens per letter here. Researchers have found the same effect in real tokenizers: some languages need several times more tokens than English for the same meaning, which costs more and fits less text in the model's window. Train on some Hindi too and the gap shrinks. Newer tokenizers and Indian models are built with this in mind.

Count your own:

Try “Tokens” in the interactive model →

Chapter 3

Words as points in space

Each token becomes a long list of numbers. Similar meanings end up close together.

A token ID like 283 says nothing about meaning. So the first thing a model does is swap each ID for an embedding: a long list of numbers, a point in a space with hundreds or thousands of directions. GPT-3's embeddings had 12,288 numbers each.

Nobody writes these numbers by hand. They are learned from one clue: words that appear in similar company tend to mean similar things. "Chai" and "coffee" both sit next to "hot", "cup" and "drink". So they end up as neighbours.

The points here are real and tiny: built from this box's short text by counting which words appear within 3 words of each other (a method called PPMI). Pick a word to see its nearest neighbours. With so little text the result is rough, but you will see drinks, places and people drift into groups. We squash about 70 directions into the 3 you can see, so trust the listed neighbours more than the picture.

In the illustrative set, eight words sit on three hand-chosen axes. Here "king − man + woman" lands exactly on "queen". In real models such vector arithmetic works only roughly and not always: a famous result, but less tidy than headlines suggest.

Embeddings also soak up bias. In our text the doctor and the engineer are "he", the nurse and the teacher "she", so doctor sits closer to engineer, and nurse to teacher. Real models learn the same kinds of patterns from the web.

Try “Embeddings” in the interactive model →

Chapter 4

Attention: every word looks at the others

The transformer lets each token pull in meaning from the tokens before it.

Read: "amma poured the chai because it was hot." What was hot? You knew at once: the chai. To get that, "it" has to look back at the other words and pick the right one. That is attention, the key idea of the transformer, from the 2017 paper "Attention Is All You Need" by a team at Google.

Each token makes three vectors from its embedding. A query: "what am I looking for?" A key: "what do I contain?" A value: "what I will pass on." Every query is compared with every key (a dot product), the scores are turned into shares that add to 100% (a softmax), and the token takes that mix of values. Now "it" carries a bit of "chai" inside it.

This is a real attention computation on 8 words, with toy embeddings and hand-set weights so each head does one clear job. In a real model all those weights are learned, and each layer runs many heads side by side: GPT-3 has 96 heads in each of 96 layers. GPT-style models also use a causal mask: a word may look only at words before it, never ahead, because it is trying to predict what comes next.

Attention is one half of a transformer block. The other half is a small neural network (see NeuralNetClear for how those learn) that works on each token alone. Stack dozens of blocks, and at the top turn the last token's vector into a score for every token in the vocabulary. That is the next-token probability from chapter 1.

Try “Attention” in the interactive model →

Chapter 5

Scale: more numbers, more text, more power

The same next-token idea, grown a million times bigger, then taught to be helpful.

Our chapter 1 model is a table of about 21,000 numbers. Big LLMs have billions of numbers, called parameters: the weights inside all those attention layers and neural networks. GPT-2 (2019) had 1.5 billion. GPT-3 (2020) had 175 billion. Some newer companies no longer say. The towers use a log scale: each step up is ten times more.

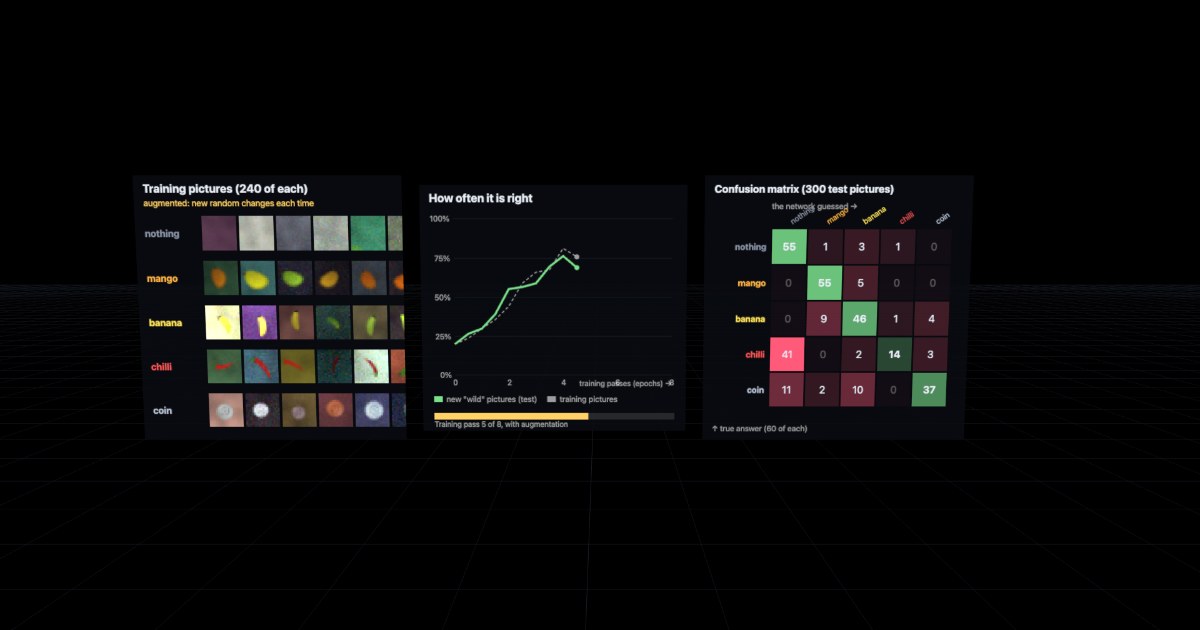
1. Pretraining. The model reads a huge pile of text, from books, websites and code, trillions of tokens, and is trained on one task: guess the next token. Each wrong guess nudges every parameter a little (the learning is the same as in NeuralNetClear, just vastly bigger). After that it can continue any text, but it is not yet an assistant.

2. Instruction tuning. It is trained further on written examples of questions and good answers. 3. Feedback. People compare pairs of answers and pick the better one, and the model is nudged towards what they prefer. This is RLHF, reinforcement learning from human feedback, or a similar method.

Why bigger helps: researchers found that the prediction error falls smoothly and predictably as parameters, data and computing grow together. A 2022 study (Chinchilla) found many models had been trained on too little text: roughly 20 tokens per parameter works better for a fixed budget.

The costs are real. Training GPT-3 was estimated at about 1,300 MWh of electricity, about the yearly electricity use of 900 people in India. Meta reported 30.8 million GPU-hours for its largest Llama 3.1 model. Each answer costs energy too: Google reported 0.24 Wh for a median text prompt to its Gemini app in 2025, about one second of a 1,000-watt microwave. Estimates vary a lot between models and studies.

Try “Scale & training” in the interactive model →

Chapter 6

Use them well: fluent is not the same as true

What LLMs do well, where they go wrong, and how to think about them.

Here our tiny model writes whole sentences, one word at a time, with the chance of each word shown under it. Every answer sounds sure. Some are copied from its text, some are new, and some new ones are false. Nothing inside the model marks the difference.

That is the big lesson for large models too. They predict likely text, so they can produce a smooth, confident answer that is simply wrong: a made-up date, a quote nobody said, a book that doesn't exist. This is called hallucination. They also absorb bias from their training text, and they can sometimes repeat rare text they saw, which matters for privacy.

What they do well: explain an idea in simpler words, draft and edit writing, summarise a long text you give them, translate, brainstorm, and help with code. What they do badly: exact facts, fresh news, sums done "in the head", and anything where being wrong is costly, unless they can check a source or run a tool.

Use them well. Give context and say what you want: "explain the monsoon to a 12-year-old in 5 lines". Ask for sources, then open them. Check numbers, names, dates and medicines against trusted sites. Don't paste passwords, Aadhaar numbers or private data. Treat the answer as a helpful first draft, not the final word.

In India, groups are building models for Indian languages: Sarvam AI (chosen in 2025 under the government's IndiaAI Mission to build a national model), Ola's Krutrim (2023) and the government-funded BharatGen (2024), alongside the Bhashini translation platform. In 2023 NPCI announced Hello! UPI, voice payments in Hindi and English, with language models developed with AI4Bharat at IIT Madras and the Bhashini programme, on a payment system that handled around 20 billion payments a month in 2025. How well such tools serve every language is still being worked out.

How to think about AI: an LLM is neither a mind nor a trick. It is a very large, very well-trained next-token predictor. That turns out to be remarkably useful and also unreliable in predictable ways. Use it like a clever helper whose work you check. Your own brain (see BrainClear) learns from far less text and knows when it doesn't know. The model mostly doesn't.

Try “Use them well” in the interactive model →

Test yourself

Frequently asked

What does a language model actually output?

A probability for every possible next piece. It scores every option for the next piece. Then one is picked, added, and the loop repeats.

You set the temperature near 0. What happens?

It always takes the most likely choice, and often repeats itself. Low temperature sharpens the odds until only the top choice is left. Safe, but it can loop.

Why does the 5-gram model copy its training text?

Its long contexts were seen only once or twice, so only one letter ever followed. With little text, a long context matches just one place in it, so the counts point to exactly what came next there.

What does an LLM actually read?

Token IDs: numbers for pieces of text. Text is chopped into tokens and each token is a number. The model works only with those numbers.

How does BPE build its tokens?

By merging the most common neighbouring pair, again and again. It starts from bytes and keeps giving the most frequent pair a new number.

Why can Hindi take more tokens than English?

Each Devanagari letter is 3 bytes, and English-heavy tokenizers learned few Hindi merges. Without learned Hindi pieces, text falls back to bytes. Training the tokenizer on Hindi too brings the count down.

What is an embedding?

A list of numbers that places a token in meaning-space. Each token ID is swapped for a learned vector. Similar tokens get nearby vectors.

How do embeddings learn that "chai" is like "coffee"?

They appear in similar company in text. Words used in similar contexts get similar vectors: "you shall know a word by the company it keeps".

Does "king − man + woman = queen" always work in real models?

Only roughly, and not always. It is a real effect but messy. Here it is exact only because the illustrative set was placed by hand.

In attention, what does a query do?

Says what this token is looking for, to be matched against keys. Each query is compared with every key; better matches get more of the attention.

What does the causal mask stop?

Looking at later words. A model that predicts the next token must not peek at tokens that come after.

Where does the transformer come from?

The 2017 paper "Attention Is All You Need". A Google team introduced it in 2017. Nearly every modern LLM is built on it.

What is a parameter?

One learned number inside the model. Parameters are the weights learned in training. GPT-3 had 175 billion.

What does pretraining teach a model?

To predict the next token in huge amounts of text. Instruction tuning and feedback come afterwards to turn it into a helpful assistant.

About how many operations does training take, per parameter per token?

About 6. Roughly 2 for the forward pass and 4 for learning, so compute ≈ 6 × parameters × tokens.

An LLM gives a confident, fluent answer. What does that tell you?

Nothing about truth: it predicts likely text. Confidence comes from how likely the words are, not from checking facts.

Why did our model say every doctor was "he"?

That was the only pattern in its training text. Models repeat the patterns in their data, including unfair ones.

Which is the best habit when using a chatbot?

Ask for sources and check important facts. Treat the answer as a first draft. Check what matters, and keep private data out.

Words worth knowing

Language model
A program that gives the probability of each possible next piece of text.
Token
A numbered piece of text, such as a word, part of a word or a byte, that the model reads.
Byte-pair encoding
Building a token vocabulary by merging the most frequent neighbouring pair, again and again.
Embedding
A learned list of numbers that places a token in a space where similar meanings sit close together.
Attention
Each token scores the others with query-key dot products and takes a weighted mix of their values.
Transformer
The 2017 architecture that stacks attention and small neural networks; the basis of modern LLMs.
Parameter
One learned number inside the model; large models have billions.
Temperature
A sampling dial: low picks the likeliest token, high spreads the choice out.
Hallucination
A fluent, confident answer that is false or made up.

Fork it. Teach with it.

This box is plain HTML, CSS and JavaScript, with no build step and no accounts. Run it yourself and it sends nothing anywhere. The code is MIT. The words, images and videos are CC BY 4.0, so you can reuse them anywhere if you credit “Glassbox, glassbox.how/e/llmclear”.

git clone https://github.com/bdeeps/llmclear.git

Built with three.js (MIT), Geist, Instrument Serif (SIL OFL 1.1).

←→ previous / next box · / search

Would you like to see the full page, with the interactive model?